How Microsoft and MIT Improved AI Weather Forecasts Six Weeks Ahead
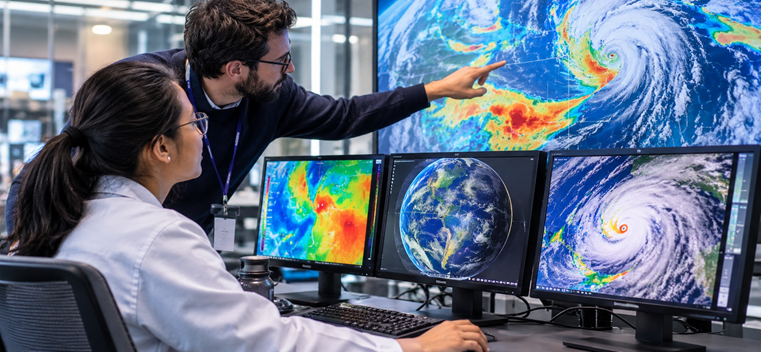
Ask a forecaster what the weather will do three weeks from now and you will not get a confident answer. Past about fourteen days, the accuracy drops sharply. Farmers planting crops and utilities buying power are making decisions on little more than a guess.
In October 2026, a Microsoft Research team with collaborators at MIT and ECMWF narrowed that gap in Nature. Their result deserves your attention for an unusual reason.
Their contribution adds nothing to the forecasting models themselves. They built a thin correction layer that runs on top of what is already deployed. It learns the mistakes those models repeat and rewrites the output before anyone reads it.
That layer then beat six operational forecasting centers in a live competition.
This article covers what breaks in the two-to-six-week range and how the correction works. This article also covers its achievements and which parts of the approach apply to models you run yourself.
Why Forecast Skill Falls Apart After Two Weeks
AI weather forecasting and physics-based prediction have both improved out to two weeks, and the paper describes forecasts at that range as enjoying "unprecedented accuracy."
Push past two weeks, and the picture changes. Writing in Nature, Hannah Guan and colleagues report that "model skill drops precipitously at subseasonal timescales", the window running two to six weeks ahead. They attribute the collapse to compounding errors and to biases built into the models. The chaotic behavior of the atmosphere supplies a third cause.
Judah Cohen, an MIT research scientist and a co-author on the paper, calls that window a "predictability desert". He traces the problem back to Edward Lorenz, who "came up with this theoretical two-week limit where beyond that, we just can’t predict weather." Cohen adds that he "never really believed that completely."
Those causes differ in how much you can do about them. Chaos sets a hard ceiling, because tiny differences in starting conditions grow until two nearly identical states end up nowhere near each other, and no amount of engineering removes that.
Systematic bias is the tractable half of the problem. A model that consistently predicts excessive warmth for a region and season likely repeats the error annually, and a mistake that repeats is a pattern you can learn.
Forecasters have corrected biases for decades. The Microsoft team changed the object being corrected, and that single move is the basis of the whole method.
What Probabilistic Bias Correction Does
Probabilistic bias correction, or PBC, is a machine learning subseasonal forecast method that corrects the probability distribution a model produces. It wraps an existing model without altering it.
A traditional correction adjusts the value. Suppose a model predicts 40 millimeters of rain and runs about 15% high in your region, so you should expect 34. PBC works a level above that. It asks how confident the forecast should be across the full range of outcomes, then rewrites those confidence levels.
The method runs in four steps, and none of them is computationally expensive.
Step 1. Turn the ensemble into probabilities. Forecast models run many simulations from slightly different starting conditions. PBC takes that spread and converts it into probabilities across climatological quintile bins, so the output states a likelihood for each band of outcomes.
Step 2. Apply two corrections side by side. The first, Debias++, adjusts the forecast for each location, date and quantile. It picks its training window adaptively. The second, Persistence++, blends the forecast with recent observations and with long-run climate averages, which lets it catch trends the forecast missed.
Step 3. Average the two and keep the result coherent. Before the two are averaged, each correction gets projected back onto a valid cumulative distribution. That projection uses isotonic regression, which finds the nearest set of values that never decrease. Without the step, the corrections could produce probabilities that contradict one another.
Step 4. Retrain every day. PBC refits daily, using only the data that existed on the issuance date. That constraint keeps the published figures honest, because no future data ever leaks into the training.
The design is deliberately light, and it can wrap a physics-based model or an AI one with equal ease.
What the Numbers Show
The team tested PBC against three base models, and how much it helped depended heavily on what it was correcting.
| Base Model |
Type |
What PBC Added |
| European Centre for Medium-Range Weather Forecasts (ECMWF) operationally-debiased model |
Physics-based |
Improved skill for 91% of pressure, 92% of temperature, and 98% of precipitation targets |
| AI Forecasting System (AIFS) |
AI |
Roughly doubled average skill, reaching 0.03 RPSS |
| PoET |
Hybrid |
Gains of 68% to 98% for precipitation and 15% to 23% for pressure, with 5% to 7% for temperature |
Read the second row carefully, because the headline number hides something. Doubling sounds dramatic until you look at where it lands. The ranked probability skill score (RPSS), measures probabilistic accuracy against a reference forecast. A score of 0.03 is small. PBC doubled a weak starting skill, and the corrected result remains low in absolute terms.
The first row is the stronger claim. ECMWF had already applied its own operational debiasing to that model before PBC ever saw it. Improving on an already-corrected baseline across 98% of precipitation targets is a harder achievement than doubling a low number.
The authors point to severe weather as the clearest practical gain, reporting that the improvements "translate into more accurate prediction of extreme events." Cohen regards this as the part that counts, saying that "extreme events might be the most impactful part of this for society." Those figures come from retrospective evaluation on historical data.
Why It Won a Live Competition
Retrospective testing invites the suspicion that a method was tuned until it worked. ECMWF’s AI Weather Quest closed off that objection by running the comparison in real time.
The team entered an ensemble called MicroDuet, which combined PBC applied to the ECMWF dynamical model with PBC applied to PoET. Their forecasts "placed first for all weather variables and lead times, outperforming the dynamical models from six operational forecasting centers," along with an international multimodel ensemble, ECMWF’s own AI system, and 34 other teams worldwide.
This ranking can be contextualized in engineering terms. The competitors included institutions with supercomputing budgets and decades of model development behind them. A correction layer retrained daily on historical errors outscored them, without reproducing any of the physics those institutions encode.
The explanation is that PBC was solving a narrower problem. Those centers work to make their simulations more faithful to the atmosphere. PBC only has to answer where this particular model has been wrong before, and narrow questions are often easier to answer well.
What Transfers to Models You Run
Weather is an extreme case among hard prediction problems, and the mechanism behind this result does not depend on that. Any production model that makes repeatable mistakes is a candidate for the same treatment.
Three ideas from this work apply directly to that.
-
Correct the output before you rebuild the model. Retraining a large model costs money and weeks. A correction layer is cheap and ships quickly, and this team took first place in a live competition with one.
-
Fix the distribution as well as the point estimate. A corrected prediction with uncorrected confidence solves half the problem. A well-calibrated model tells you when to trust it, which matters whenever a person or a downstream system acts on its output.
-
Treat systematic error as a first-class signal. You cannot correct a bias you have never measured. That is ordinary monitoring work, covered in this guide to AI model observability. It supplies the input the whole method depends on.
The daily retraining deserves separate attention. PBC stays useful because it refits constantly as conditions shift, which makes it a scheduling and infrastructure commitment more than a modeling one. The practices in this guide to building scalable AI pipelines apply directly to running a correction layer in production.
Knowing when to correct and when to retrain is its own judgment call. This overview of techniques for optimizing AI models covers the alternatives worth weighing first.
Where the Method Stops
The authors state the limits plainly, and you should carry them into any comparison you make.
PBC corrects predictable error and does not relearn atmospheric dynamics, so it complements the models it wraps and cannot replace them. It also cannot run on its own. An upgrade to an input model forces a retrain, because the biases PBC learned belonged to the previous version.
The evidence base has edges too. Real-time competition results cover two seasons, while most of the evaluation is retrospective across 2016 to 2024. The severe-flood analysis rests on 88 events, a small sample for any claim about rare occurrences.
None of this undercuts the result. It does mean the method is early, and that a correction layer inherits the fate of whatever sits beneath it.
Conclusion
The lesson here has little to do with weather. A team with serious modeling resources looked at a hard problem and chose to fix the output of existing models, and the correction outscored the operational centers it was measured against.
Systematic error is predictable by definition, which means a model can learn it. Your own models repeat their mistakes in ways you can measure, and correcting them costs a fraction of what a retrain does.
Pull your production model’s errors from the past quarter and check whether they cluster. A pattern that appears by segment or by input range is the opening this team exploited.